Three new PhD students join GRC
Ainara Garcia and Anwar Benhnini began their PhDs in the Department of Computer Science at Illinois Institute of Technology with the fall 2026 term, which started on August 17, and joined the Gnosis Research Center. They complete a 2026 cohort with Zia Uddin Chowdhury, who arrived in January and has already presented his first GRC poster.
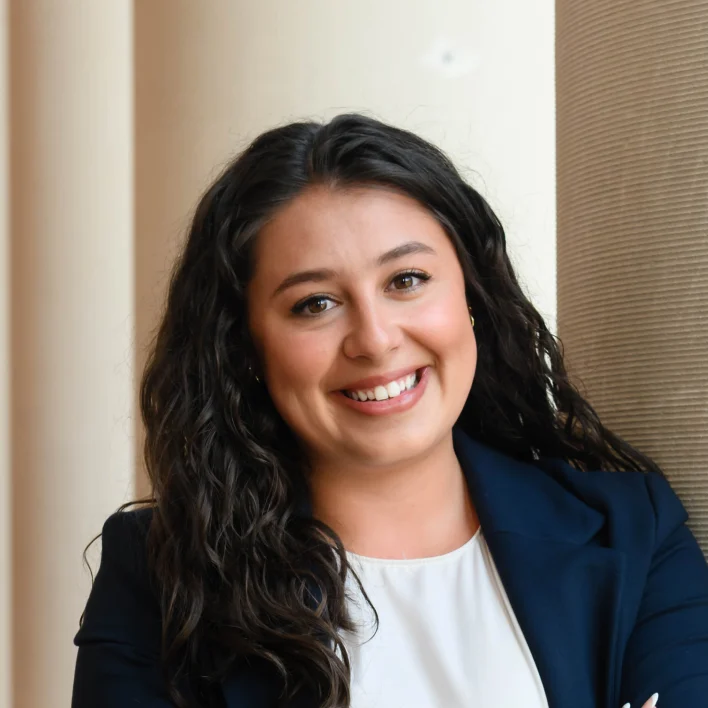
Ainara Garcia: communication for AI at scale
Garcia earned a BS in Computer Engineering from Clemson University. She is advised by Xian-He Sun and Bogdan Nicolae and works on MPI4AI, an NSF Frameworks project led at Illinois Tech by Nicolae with Tennessee Technological University, the University of Tennessee, Knoxville, and Stony Brook University. MPI4AI extends Open MPI, the open-source implementation of the Message Passing Interface, with native GPU communication, collective operations designed for AI, integration with compute streams and fault tolerance. The project targets three AI patterns: neural architecture search with transfer learning, key-value prefix caching in LLM inference, and large-scale data-parallel training. It also aims to carry its extensions into the MPI-5 and MPI-6 standards.
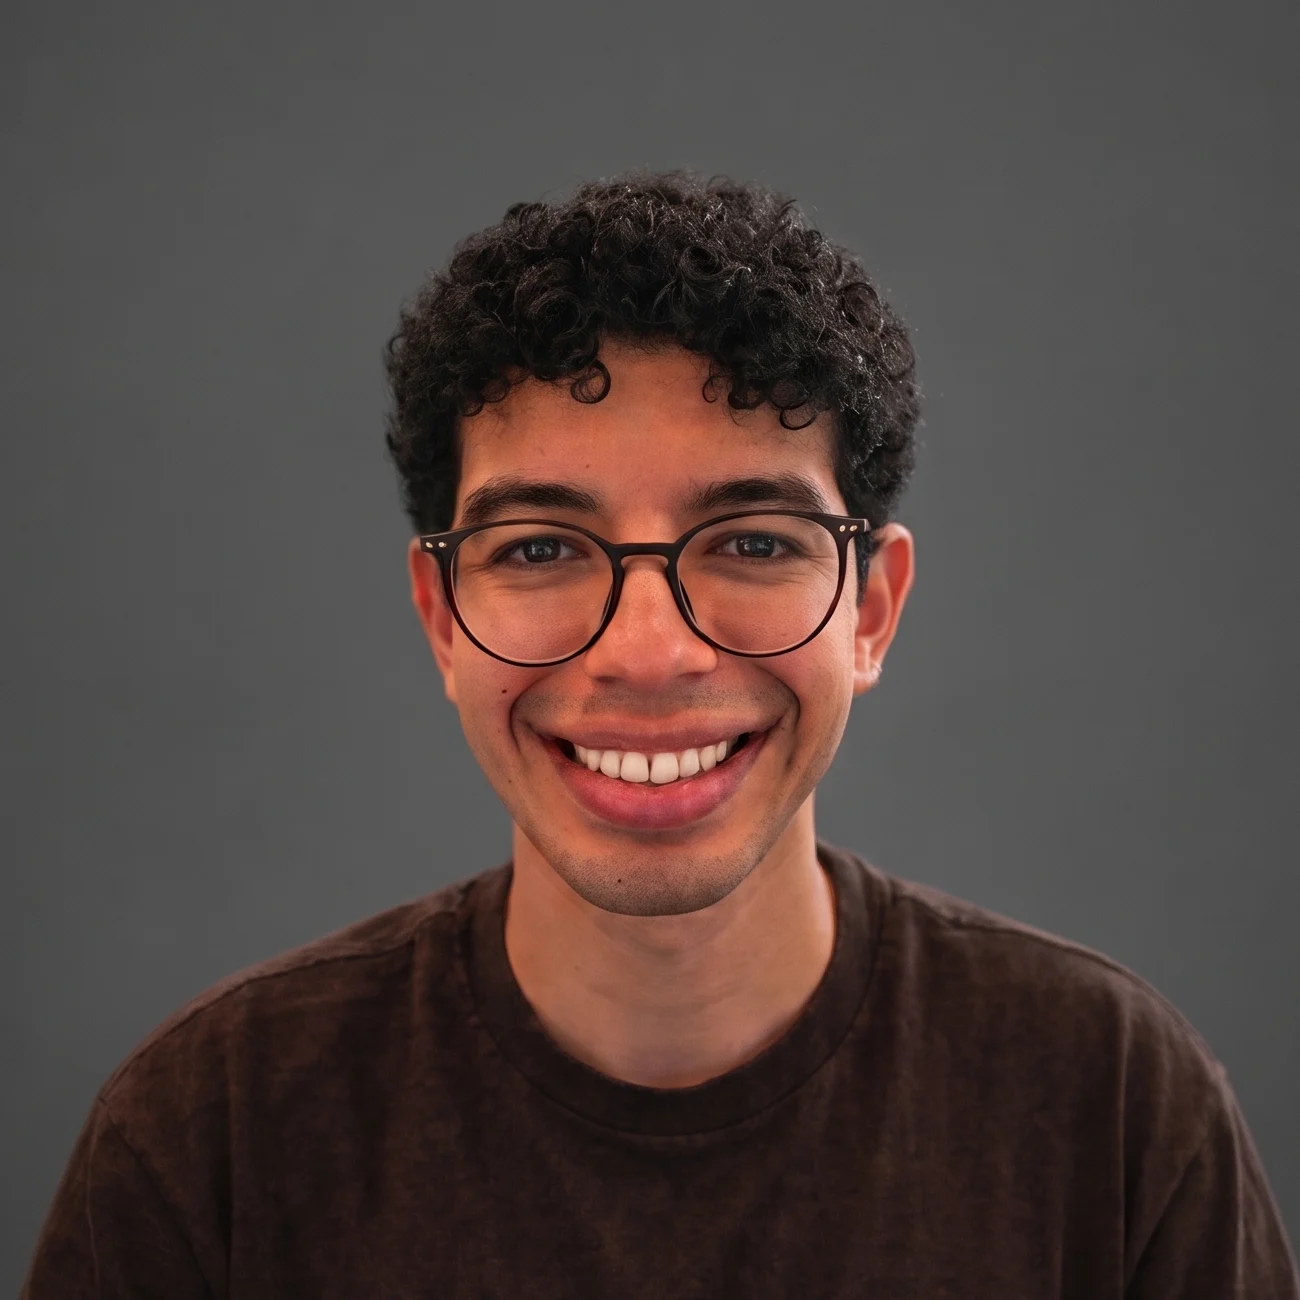
Anwar Benhnini: memory-centric computing
Benhnini is advised by Xiaoyang Lu and Sun and works on UniMCC, an NSF Computer Systems Research project shared with the University of Iowa. UniMCC is building a full-stack system for hardware that pairs near-memory data processors with a disaggregated, shared memory pool. The work crosses layers: architecture, hardware and software interfaces, compiler support, runtimes and performance models. Sun is the principal investigator of the Illinois Tech award and Lu leads the project in the lab. In 2026 Lu was first author on two UniMCC papers about long-sequence LLM inference: an I/O analysis of attention at ASPLOS and a processing-in-memory accelerator for hybrid sparse attention at IPDPS.
Zia Uddin Chowdhury: KV cache survivability
Chowdhury joined in January 2026, advised by Anthony Kougkas and Sun, and works on IOWarp. At the 13th Greater Chicago Area Systems Research Workshop (GCASR 2026) at Northwestern University on May 11, he presented the poster "Pre-RoPE versus Post-RoPE: Trading Per-Step Compute for KVCache Survivability", with Jaime Cernuda, Jie Ye, Kougkas and Sun.
LLM inference engines cache attention keys and values so they are not recomputed at every decoding step. The usual approach stores keys after applying rotary position embeddings (RoPE), which bakes each token's position into the cache. When a long context overflows and the oldest tokens are dropped, the surviving keys carry stale positions. Storing keys before RoPE and rotating them at attention time avoids that problem but costs compute on every step.
The poster measured both sides of the trade-off with vLLM and Llama 3.1 8B Instruct on NVIDIA GH200 nodes of the Delta system, using LongBench NarrativeQA at 4K to 32K context lengths. Pre-RoPE storage raised time to first token by 10% to 30% and lowered decode throughput by 1.8 to 3.1 times. In return, when half of the cache was truncated, re-rotating pre-RoPE keys took about 30 times less time than the re-prefill baseline, while naive slicing of a post-RoPE cache inflated perplexity by 30 to 65 times.
Learn more
- Ainara Garcia's profile
- Anwar Benhnini's profile
- Zia Uddin Chowdhury's profile
- Pre-RoPE versus Post-RoPE poster at GCASR 2026 and poster PDF (opens in a new tab)
- MPI4AI NSF award OAC-2514056 (opens in a new tab) and project page
- UniMCC project page
- IOWarp project page
- Illinois Tech academic calendar (opens in a new tab)