ChronoLog
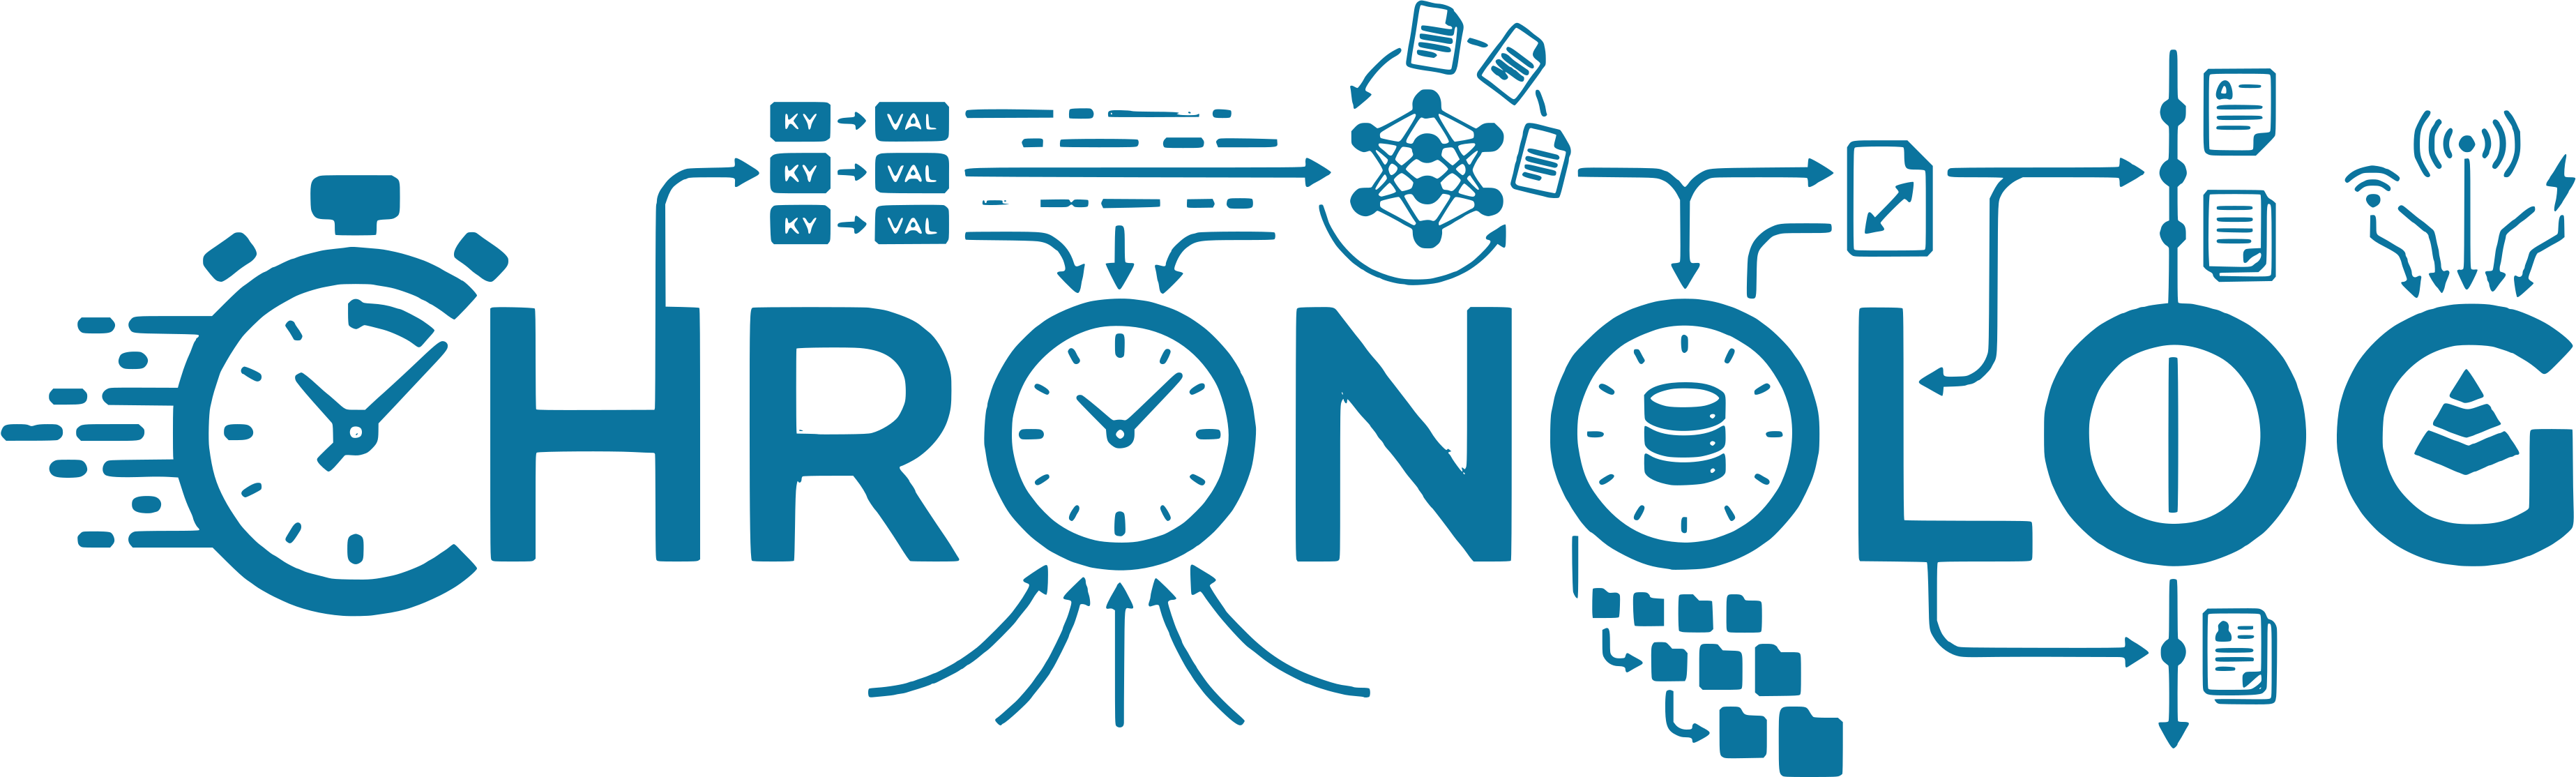
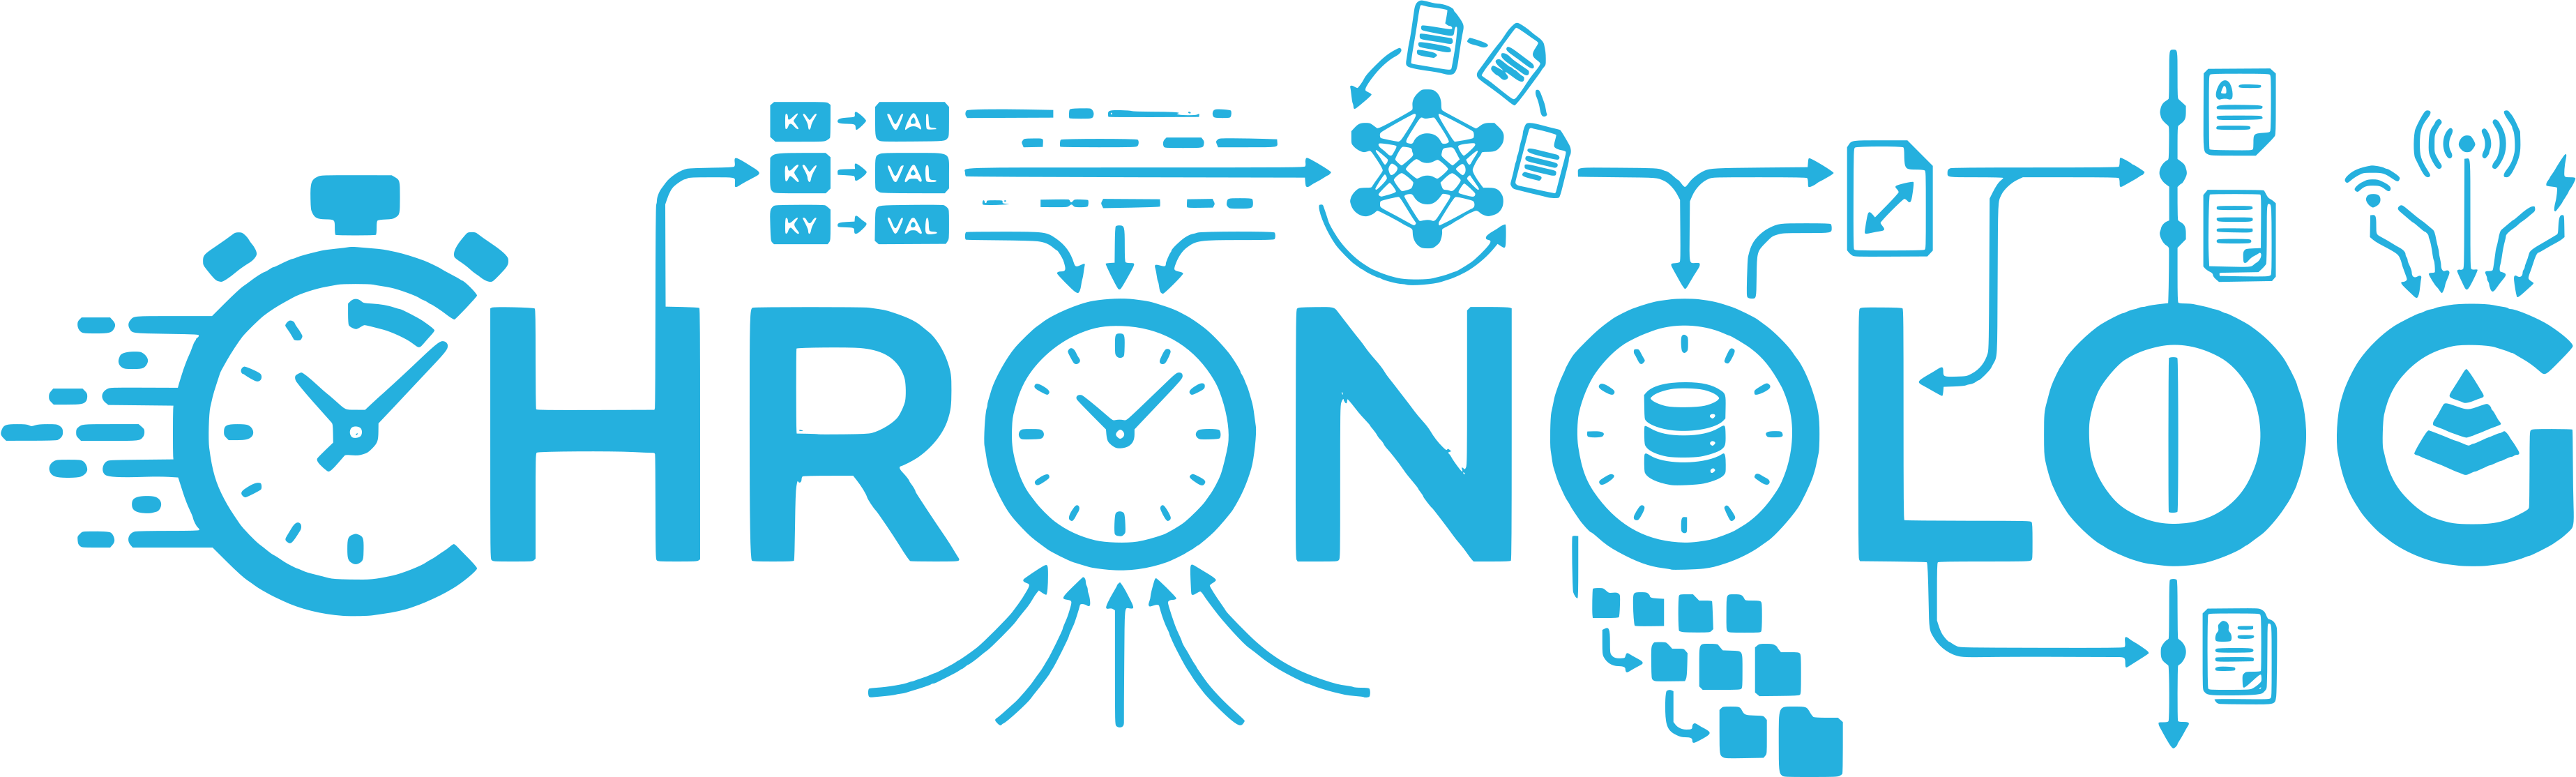
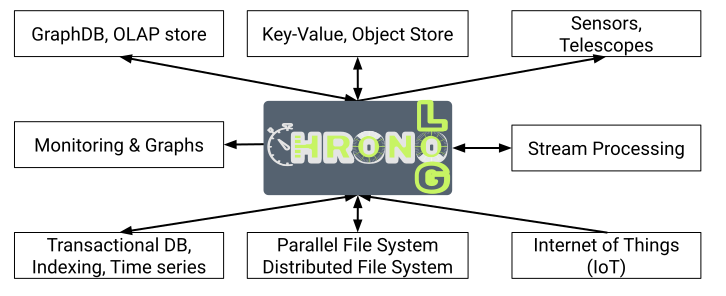
ChronoLog is a distributed shared log for activity and provenance data. It uses synchronized physical clocks to order entries without a centralized sequencer. It distributes records across nodes for throughput and across storage tiers for capacity. The MSST'20 paper reports more than one million tail operations per second and an order-of-magnitude improvement over the systems evaluated.
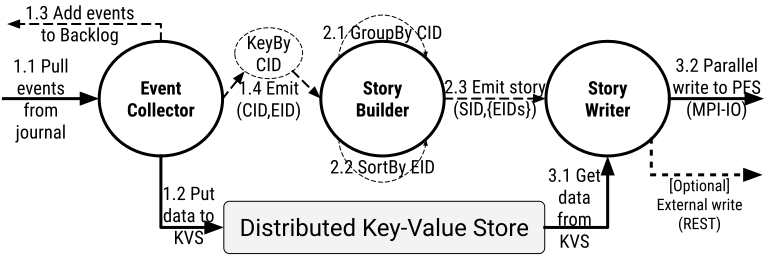
The software exposes concurrent append, tail-read, and historical replay operations. Its service pipeline ingests events close to compute, assembles them into time-ordered stories, and moves them from memory and local storage to archival systems.
Why Physical Time
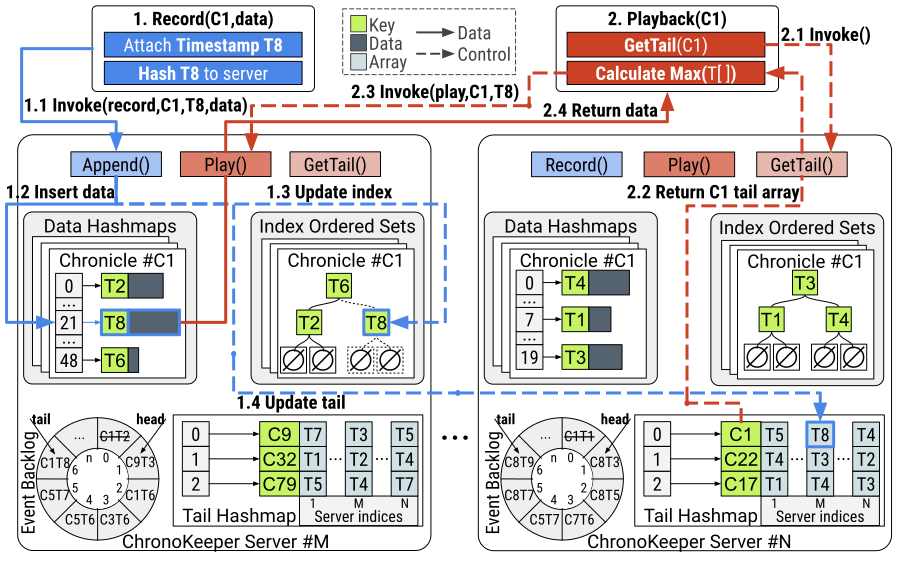
A shared log must establish one order while many writers append concurrently. Centralized tail metadata and sequencers can become points of contention. Retention limits and offline rebalancing also make it difficult to expand capacity as an activity stream grows.
ChronoLog assigns order from synchronized physical clocks. This removes sequencing from the append path and makes new entries immediately visible. Its multiple-writer, multiple-reader model supports concurrent access, while automatic tiering moves older data through DRAM, NVMe, burst buffers, and parallel file systems.
System Design
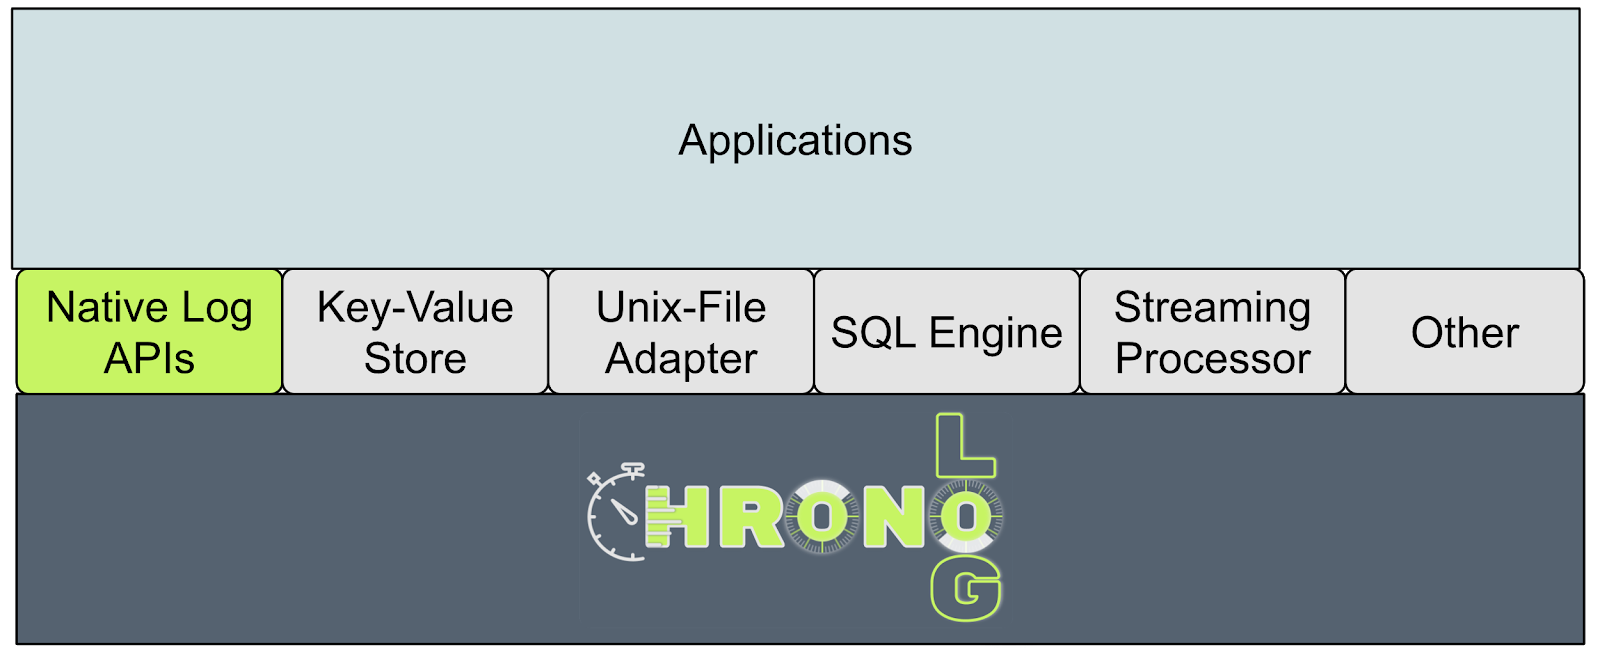
ChronoLog distributes data in three dimensions. Events are spread horizontally across nodes, vertically across storage tiers, and temporally by timestamp. This organization combines concurrent ingestion with time-range retrieval and elastic capacity.
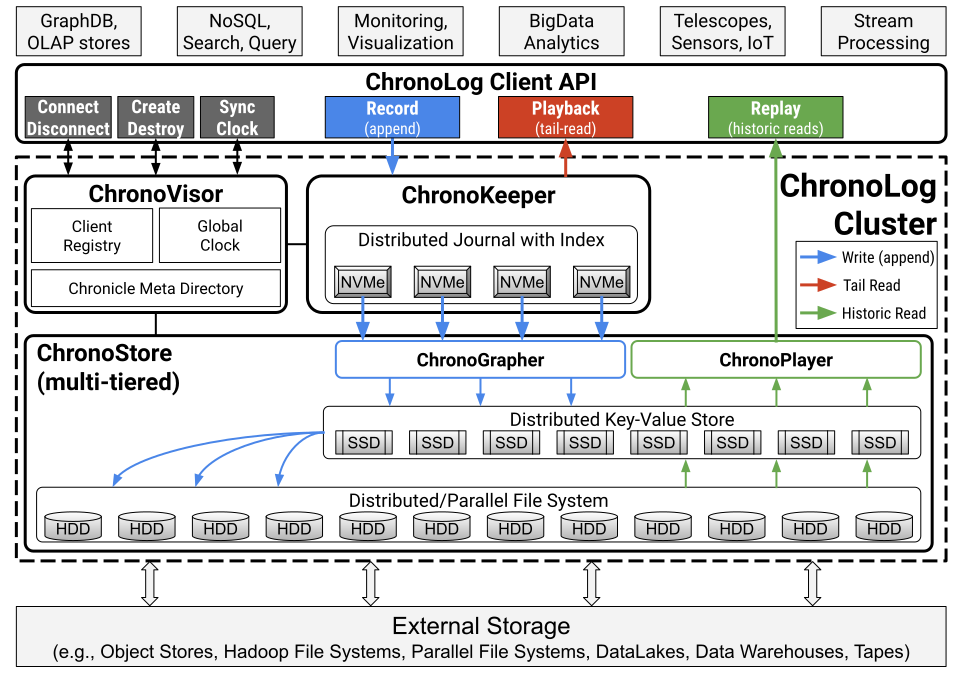
- ChronoVisor coordinates clients, chronicle metadata, and time synchronization.
- ChronoKeeper ingests events through RDMA and serves
record()andplayback()tail operations from a distributed journal. - ChronoStore manages intermediate and archival storage resources.
- ChronoGrapher collects events, assembles stories, and writes them through an elastic streaming pipeline.
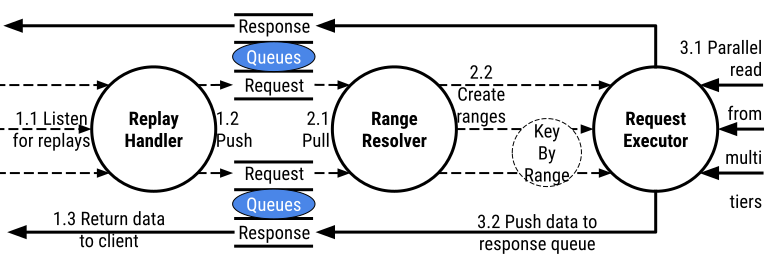
- ChronoPlayer merges parallel reads across available tiers into one time-ordered stream for
replay()requests.
Published Results
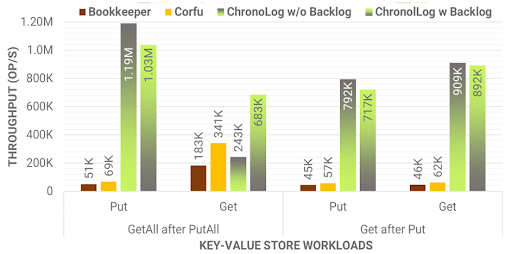
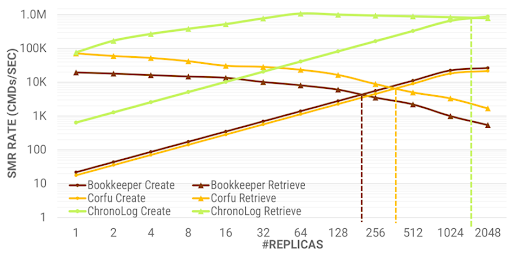
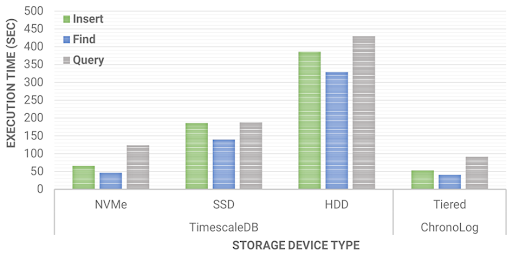
The MSST'20 evaluation studies a key-value store, state-machine replication (SMR), and a time-series analysis kernel. ChronoLog reaches more than one million put operations per second in the key-value workload, and sustains SMR throughput up to approximately 1,900 replicas, about 5 times more than BookKeeper and Corfu.
Published at MSST 2020. Read the paper (opens in a new tab)
Software and Integrations
ChronoLog v3.0.0 (opens in a new tab), released in May 2026, completes a client API cleanup, adds ChronoSQL and a simple ChronoPubSub plugin, and brings the MCP server into the main repository. The MCP server exposes chronicle creation, recording, replay, and time-range queries to compatible AI agents through the IOWarp CLIO Kit.
The public integrations roadmap (opens in a new tab) presents ChronoKVS and the MCP server as available integrations. It labels the SQL, publish-subscribe, and ML training integrations as coming soon.
ChronoLog v3.1.0 (opens in a new tab) (September 2026) added on-demand tail reads from keeper memory, a combined replay stream in ChronoPlayer, and an LDMS store plugin; v3.1.1 followed as a maintenance release. The current release, ChronoLog v3.2.0 (opens in a new tab) (October 2, 2026), keeps every sealed chunk on its keeper until ChronoGrapher confirms it archived, and lets a replay read events that are not yet archived directly from the keepers. Clients built against 3.1 must be rebuilt for 3.2.
Current research focuses on the extension interface, integration with IOWarp, and time-ordered memory for AI agents.
ChronoLog 4.0, in development: a new era in distributed agentic memory for swarms
ChronoLog 4.0 extends the shared log from activity and provenance data to the memory of multi-agent scientific systems. Its design records the actions, dependencies, models, tools, outcomes, and sharing policy of each agent as typed events. ChronoLog's physical-time ordering supplies the distributed log, and tiered placement from Hermes informs where records live across DRAM, NVMe, and persistent storage.
The research asks how agent-aware indexes and causal views can support replay of an autonomous workflow, and how each institution can keep control of what it shares. Semantic retrieval is treated as a replaceable ranked index over typed records, not as proof that two events mean the same thing. The design targets federated environments such as the National Data Platform, in collaboration with the University of Utah. ChronoLog 4.0 is in the design stage and has no release yet.