DTIO
DTIO expresses data movement, format translation, ordering, and dependencies as composable DataTasks. Its distributed runtime intercepts familiar I/O interfaces, schedules work across storage tiers, and records task provenance for replay after faults. The SSDBM'25 paper reports 49.6% better I/O performance for online translation with DataTask caching than for offline translation.
The Problem
HPC applications, Big Data frameworks, and ML pipelines use different I/O interfaces and data formats. Connecting them often requires offline conversion, which adds I/O and interrupts the pipeline. DTIO instead treats data movement and translation as schedulable tasks with explicit format semantics.
Research Contributions
The DataTask Abstraction (SSDBM'25)
Each DataTask contains a data operation, its input and output formats, ordering constraints, and dependencies. The runtime can compose and schedule these units across the complete pipeline:
- Transparent format translation. DTIO converts POSIX, HDF5, and NumPy calls into DataTasks and maps between source and destination formats.
- Online translation with caching. DTIO translates data on demand and caches DataTasks for reuse. The paper reports a 49.6% improvement over offline translation.
- Asynchronous I/O and aggregation. DataTasks overlap computation with grouped data movement.
- Fault recovery. Provenance records allow DTIO to replay the work associated with a failed partition.
Architecture
DTIO implements a six-stage I/O processing pipeline:
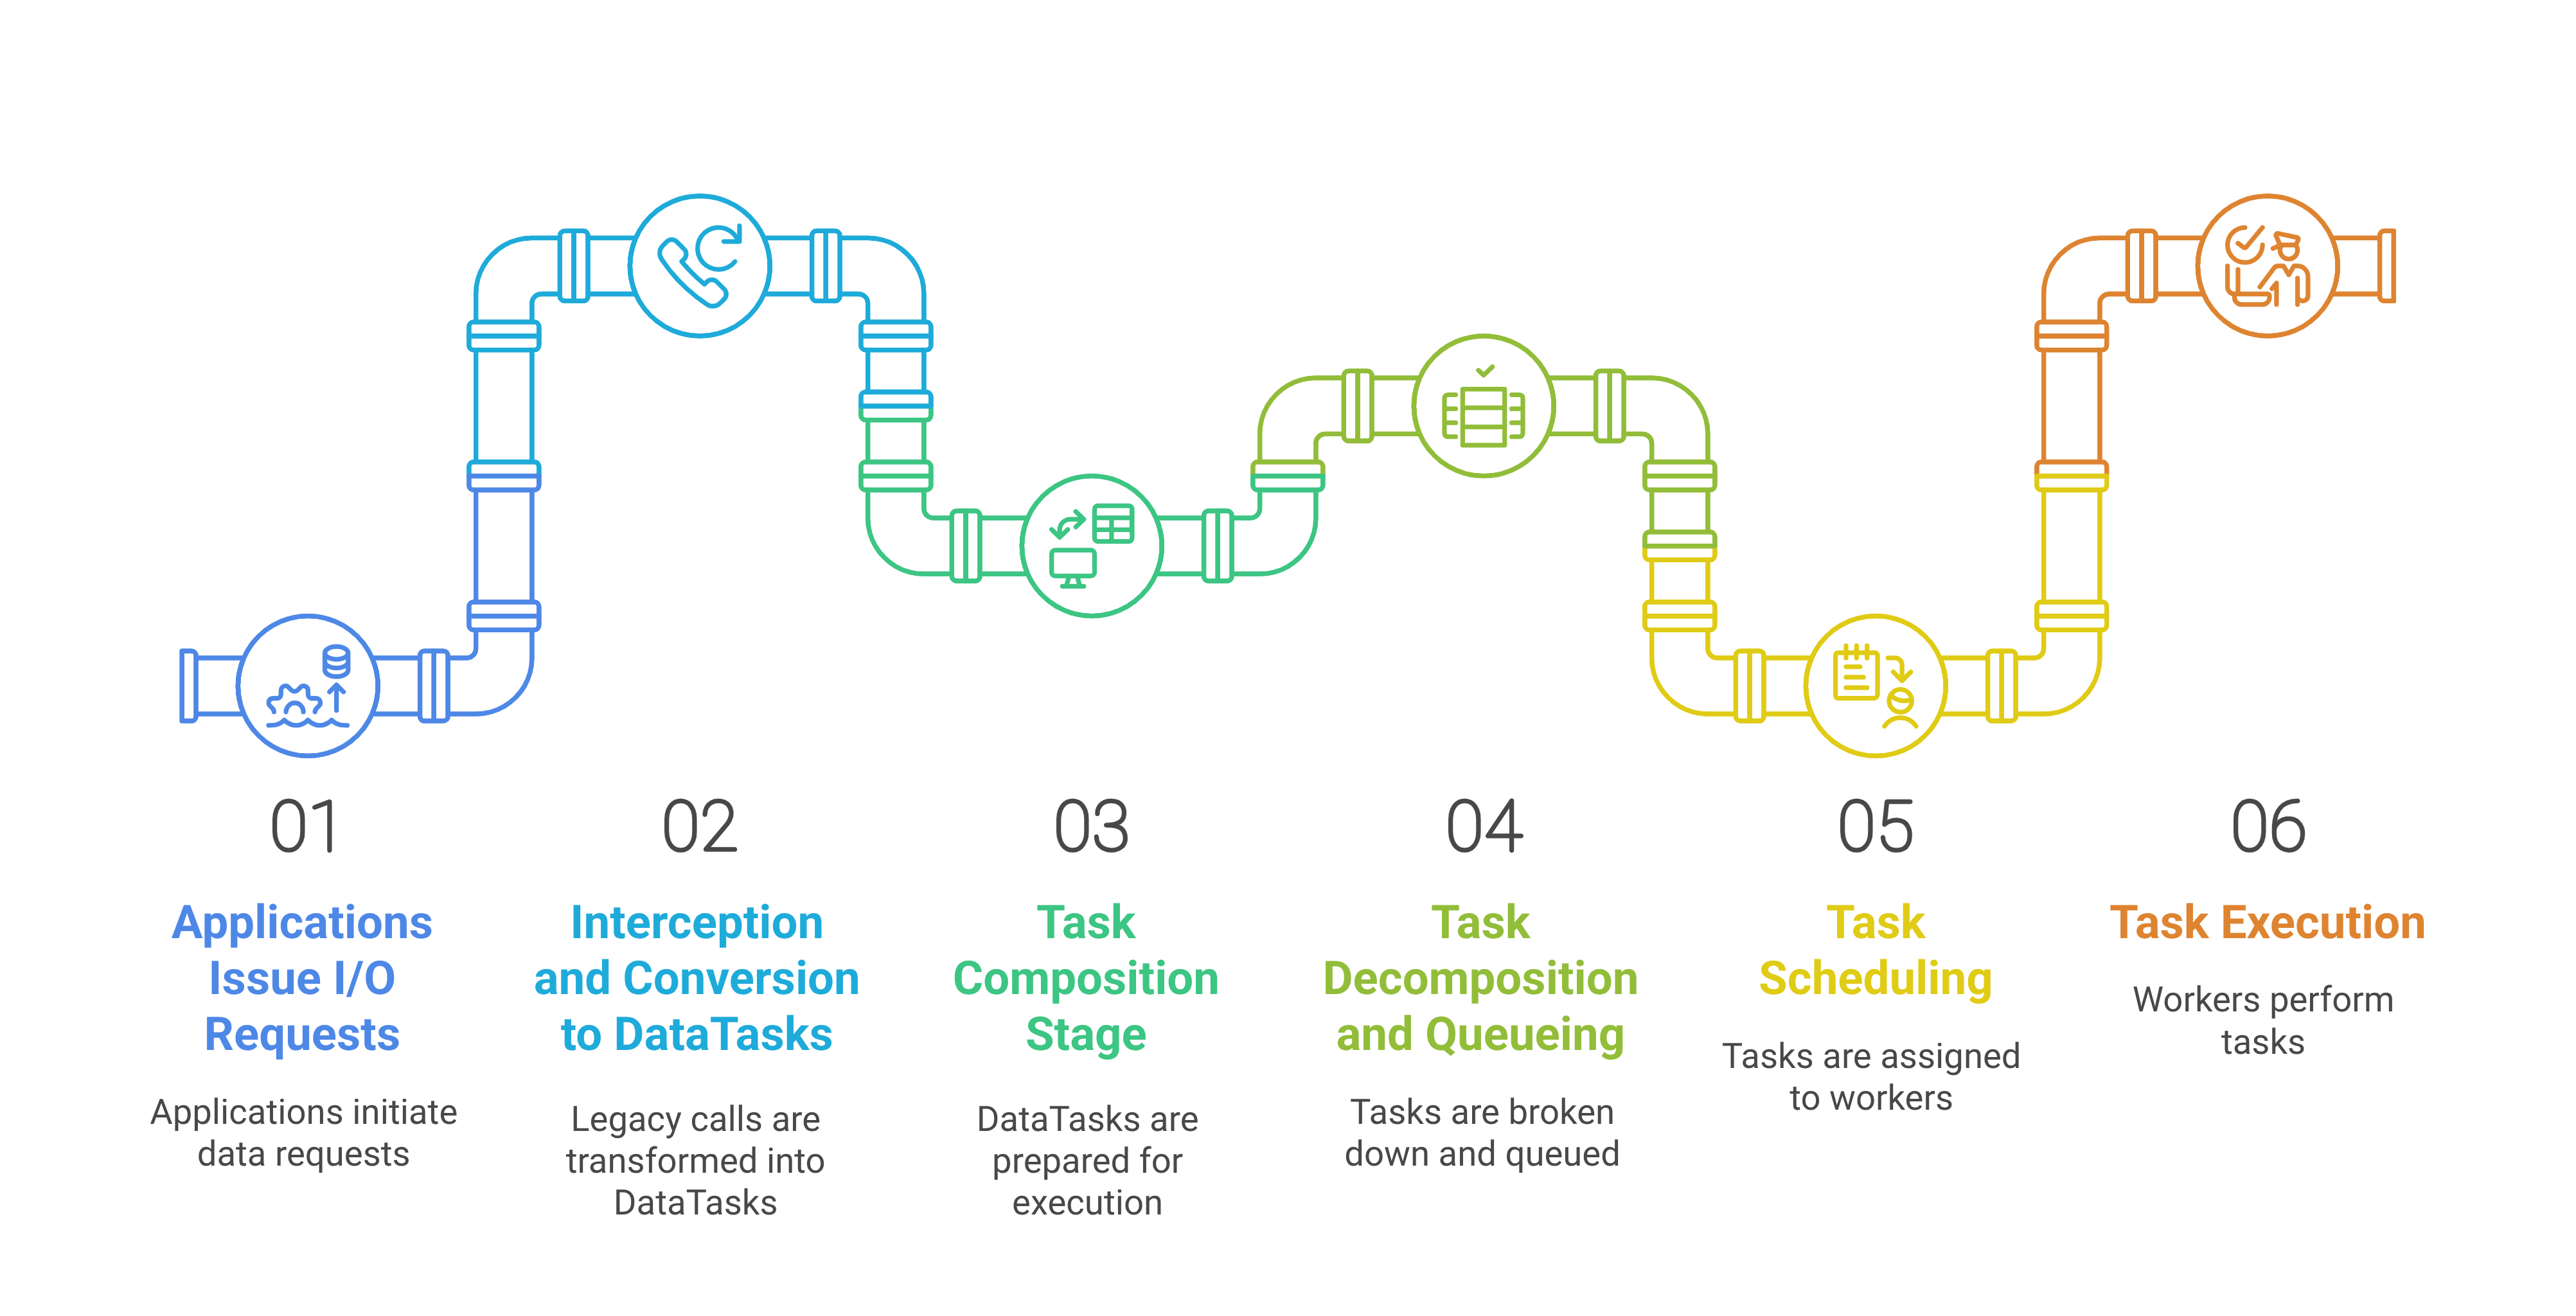
- Application I/O. Applications issue requests through native interfaces such as POSIX
readandwrite, HDF5, and NumPy. - Interception. DTIO's shim layer converts legacy I/O calls into DataTasks.
- Task composition. The runtime identifies format translations, constructs dependency graphs, and detects caching opportunities.
- Decomposition and queuing. Composite tasks become atomic operations in distributed queues.
- Scheduling. Constraint-based scheduling assigns tasks by executor load, data locality, and storage-tier latency.
- Execution. DataTask executors perform each operation on the appropriate tier and update provenance records.
Performance Results
Results reported in the SSDBM'25 paper:
Accelerated I/O Resolution
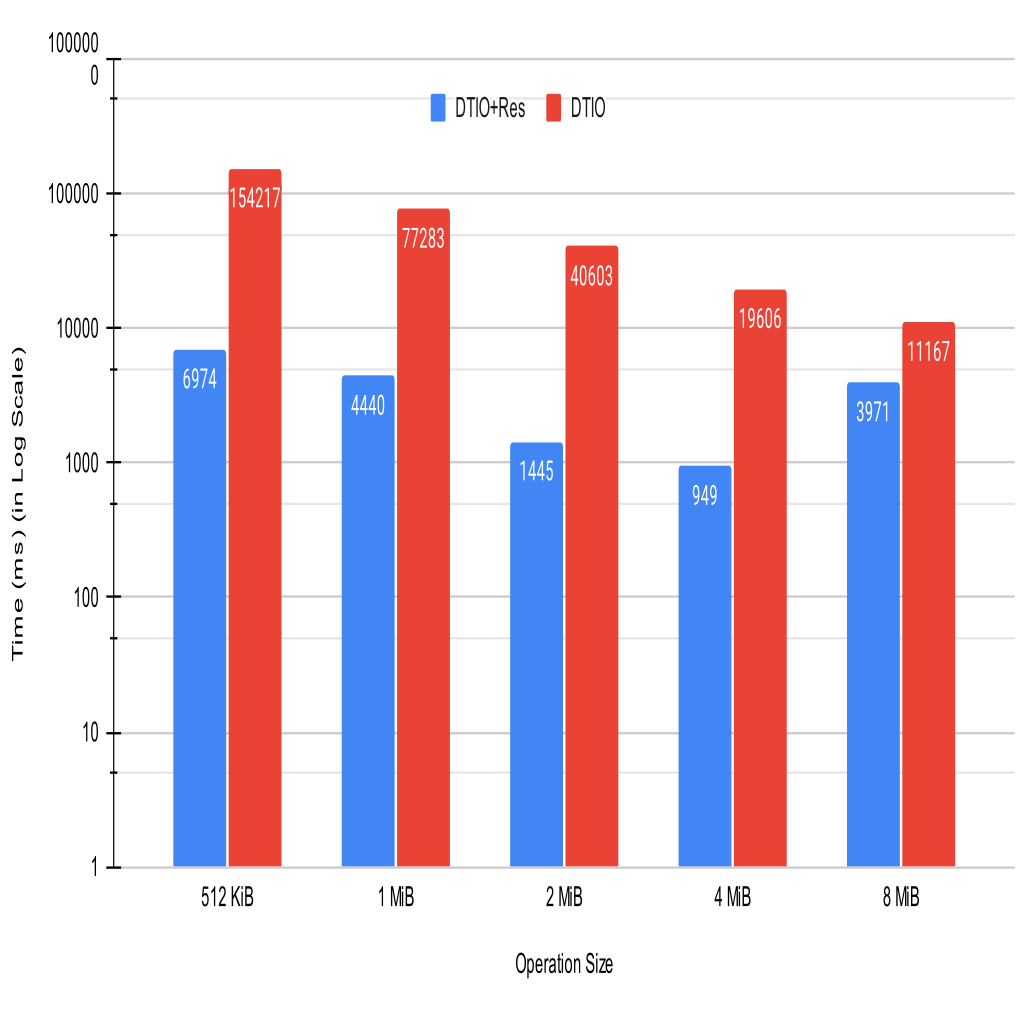
DTIO's Accelerated I/O resolution stores DataTasks in a circular buffer, so subsequent tasks retrieve data from local memory instead of re-executing the pipeline. Read time drops by 95.5% at 512 KiB and 64.4% at 8 MiB, an average reduction of 89.2%. Write overhead is at worst 12%.
Data Staging and Prefetching
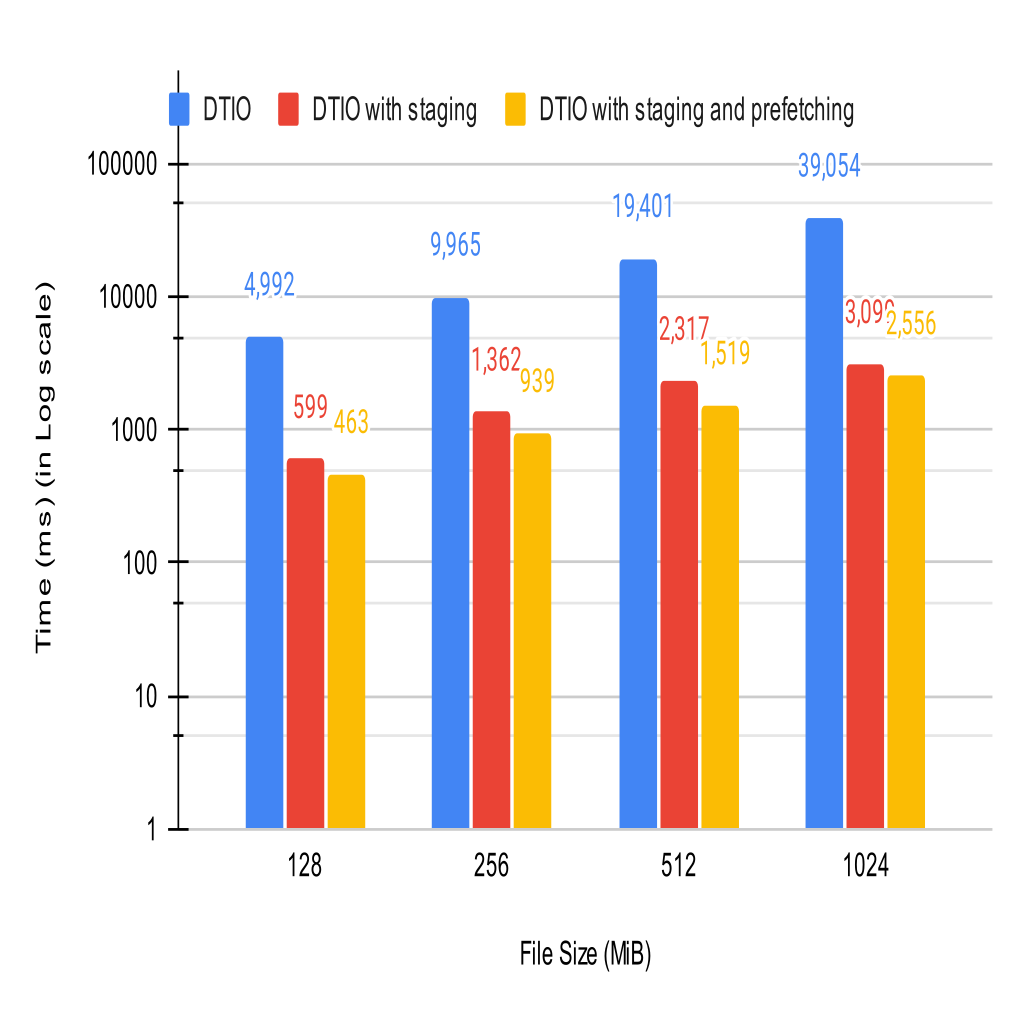
DTIO's data policy lets DataTask executors stage data before read operations arrive. Staging improves read performance by 88.6% over DTIO without staging; adding asynchronous prefetching to client circular buffers yields a further 3.1%, for a total of 91.7%.
End-to-End Evaluation with PtychoNN
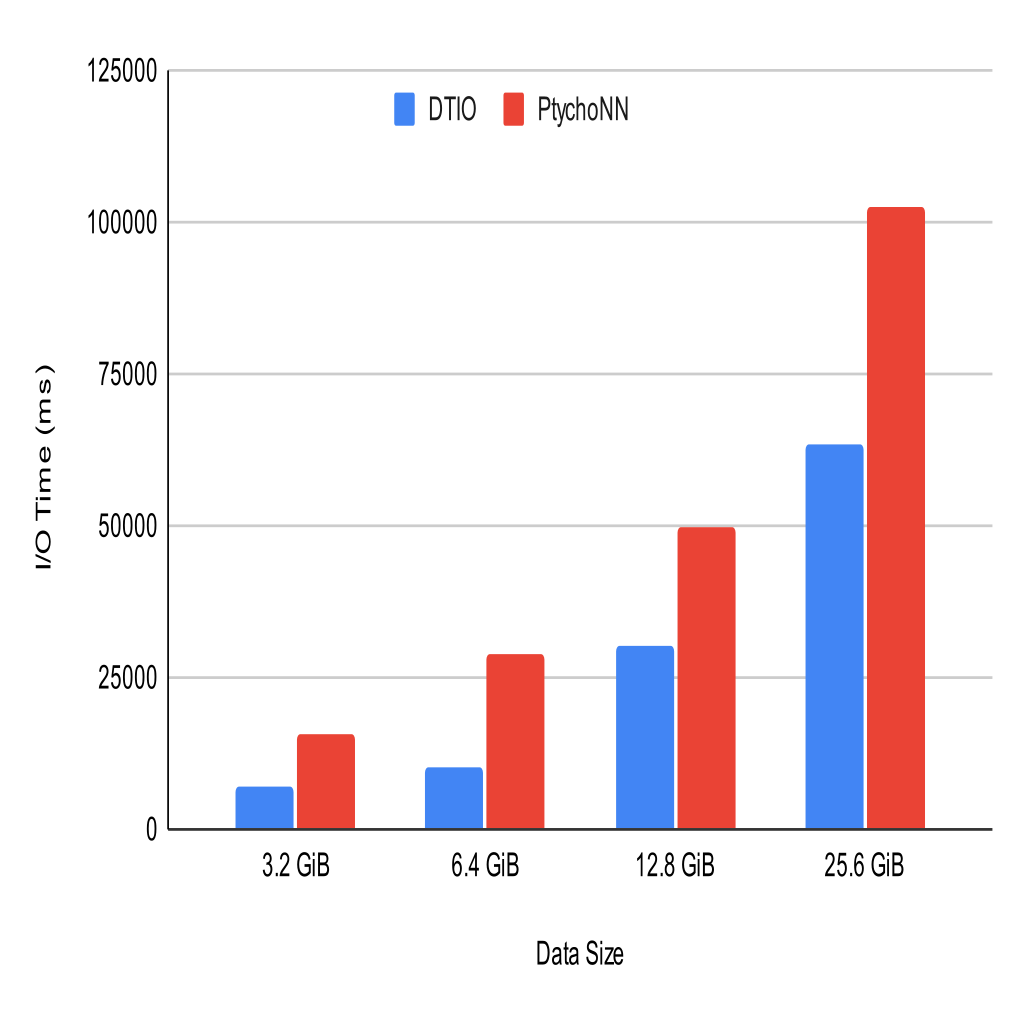
PtychoNN consists of a producer reading HDF5 simulation data and converting it to NumPy, and a consumer reading NumPy as PyTorch tensors. With DTIO as intermediary, producer and consumer run at the same time: DTIO provides access to partial results, so the full dataset does not have to be converted before training begins. I/O performance improves by 38% for 25.6 GiB workloads and 65% for 6.4 GiB workloads, an average of 49.6% (21.6 seconds of I/O time saved).
DataTasks in CLIO
DTIO's translation, caching, staging, aggregation, and splitting mechanisms were reimplemented in the CLIO runtime of IOWarp. The DTIO repository (opens in a new tab) preserves the published prototype. The August 2026 final report records about 5 times better IOR performance after the port at 1,000 Aurora nodes and a 3 times speedup for GPU-initiated DataTasks with tiering.
The same task and provenance model supports four continuing research threads:
- DTSchedule selects and places compressed data across storage tiers. The final report evaluates it across seven containerized Aurora workflows.
- AgentRecall rewinds multi-agent workflows from provenance checkpoints in CLIO and IOWarp storage. It was presented as a GCASR 2026 poster.
- Agent Error Simulator injects controlled agent errors to test recovery. The paper was accepted at eScience'26 (conference listing (opens in a new tab); code (opens in a new tab)).
- NeuroPress studies GPU-resident adaptive compression. Eternia studies tiered, compressed GPU memory in CLIO. Both extend DataTasks into GPU-resident data paths.
DTIO was developed with Argonne National Laboratory. It extends the LABIOS label abstraction into a task-based runtime.