UniMCC
UniMCC is developing full-stack support for systems that combine near-memory data processors with disaggregated shared memory. The project aligns architecture, hardware and software interfaces, code generation, runtime support, and performance models so data-intensive applications can use those resources as one memory-centric system.
Published Systems
CHROME: Concurrency-Aware Holistic Cache Management (HPCA'24)
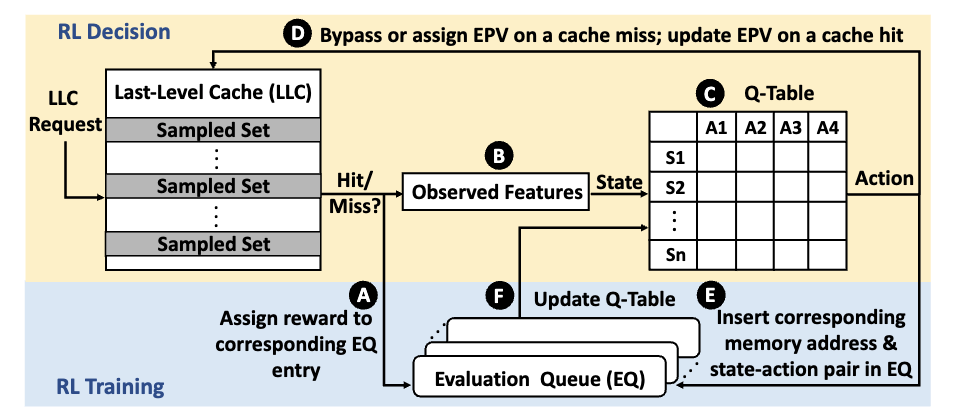
CHROME (opens in a new tab) coordinates cache replacement, bypassing, and prefetching through concurrency-aware online reinforcement learning. It adapts decisions from program features and system feedback. The HPCA 2024 paper reports up to 13.7% higher performance than LRU in multicore systems.
ACES: Adaptive and Concurrency-Aware Sparse Matrix Accelerator
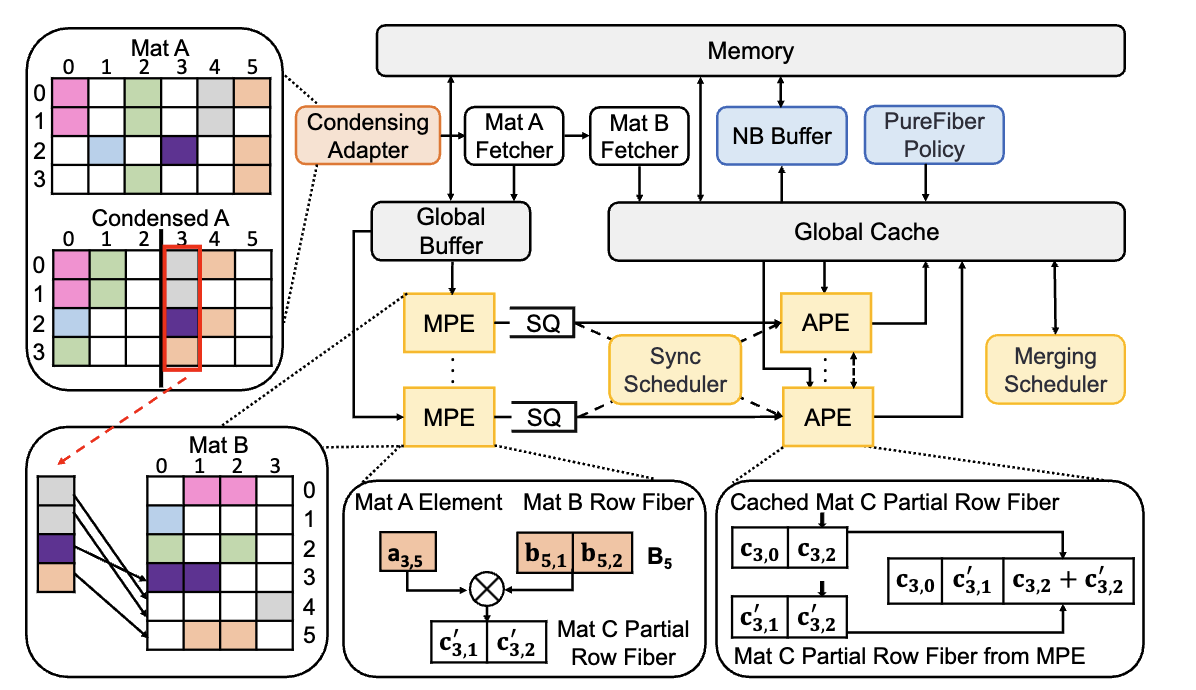
ACES (opens in a new tab) accelerates sparse matrix-matrix multiplication with an execution flow that adapts to each sparse pattern. A concurrency-aware global cache and a non-blocking buffer balance reuse, parallelism, and synchronization. The ASPLOS 2024 paper reports a 2.1x speedup over the accelerators it compared against.
2026 Results
Three published papers extend UniMCC's cross-layer approach. Zion develops a comprehensive, adaptive, and lightweight hardware prefetcher. I/O Analysis Is All You Need analyzes the I/O behavior of long-sequence attention to guide hardware and software co-design. I/O-Aware PIM Acceleration applies hybrid sparse attention to processing-in-memory acceleration for long-sequence LLM inference.
Compiler and Code Generation Work
TrackFM: Compiler-Based Far Memory
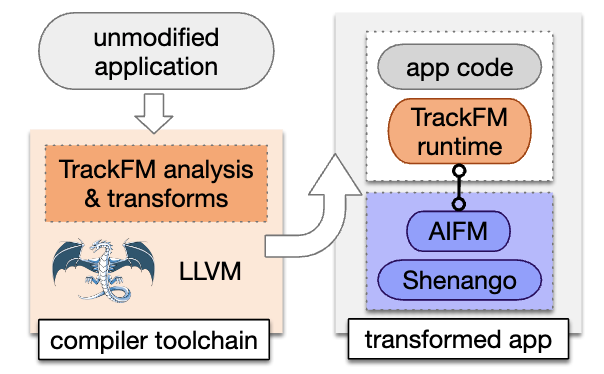
TrackFM, published at ASPLOS 2024 (opens in a new tab) by Brian Tauro, Brian Suchy, Simone Campanoni, Peter Dinda, and UniMCC co-PI Kyle Hale, is a compiler and runtime approach for running unmodified applications with far memory. LLVM passes inject access guards and connect applications to the AIFM runtime. Fast paths and loop chunking reduce redundant checks.
CUDA Code Generation for KGE Score Functions
A second active direction generates CUDA code for knowledge graph embedding score functions. It adds batched scalar-vector, vector-vector, and matrix-vector operators for fusion, then uses runtime inspection to cache unique data indices in shared memory.